6.4.1 General Bayesian Estimators
The Bmse( ) is given by:
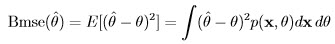
is one specific case for a general estimator that attempts to minimize the average of the cost function,  (ϵ), that is the Bayesian risk
 = E[(ϵ)] where ϵ = (θ -). Figure 6.1
shows the plots of three different cost functions of wide interest and the discussion about which one of the central tendencies of the posterior PDF gets emphasised with choice of these cost functions is given below:
- Quadratic: (ϵ) = ϵ² which yields = Bmse(). It is already shown that the estimate to minimize = Bmse() is:
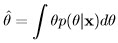
which is the mean of the posterior PDF.
- Absolute: (ϵ) = |ϵ| The estimate, , that minimizes = E[|θ -|] satisfies:
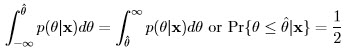
which is the median of the posterior PDF.
- Hit-or-miss:
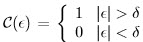 where δ is a very small threshold. Note that a uniform penality is assigned here to all errors greater than δ.
The estimate that minimizes the Bayes risk can be shown to be:
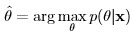
which is the mode of the posterior PDF, i.e., the value that maximizes the PDF.
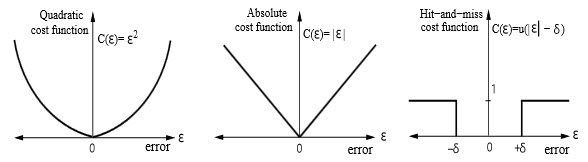
Figure 6.1: Common cost functions used in finding the Bayesian etimator
For the Gaussian posterior PDF, it should be noted that the mean, the median and the mode are identical. Of most interest are the quadratic and hit-or-miss cost functions which, together with a special case of the later, yield the following three important classes of estimators:
- MMSE Estimator: The minimum mean square error (MMSE) estimator which has already been introduced as the mean of the posterior PDF.
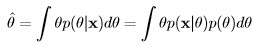
- MAP Estimator: The maximum a posteriori (MAP) estimator which is the mode (or maximum) of the posterior PDF.
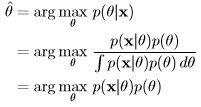
- Bayesian ML Estimator: The Bayesian maximum likelihood estimator which is the special case of the MAP estimator where the prior PDF, p(θ), is uniform or non-informative:
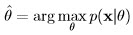
Noting that the conditional PDF of x given θ, p(x|θ), is essentially equivalent to the PDF of x parameterized by θ, p(x|; θ), the Bayesian ML estimator is equivalent to the classical MLE.
Comparison among the three types of Bayesian estimators:
- The MMSE is preferred due to its least-squared cost function but it is also the most difficult to derive and compute due to the need to find an expression of the posterior PDF, p(θ|x) in order to integrate ∫ p(θ|x)dθ.
- The hit-or-miss cost function used in the MAP estimator though less “precise” but it is much easier to derive since there is no need to integrate, only find the maximum of the posterior PDF p(θ|x) which can be done either analytically or numerically.
- The Bayesian ML is equivalent in preference to the MAP only in the case where the prior is non-informative, otherwise it is a sub-optimal estimator.
- Like the classical MLE, the expression for the conditional PDF, p(x|θ) is easier to obtain rather than that of the posterior PDF, p(θ|x). Since in most cases knowledge of the prior is not available so, not surprisingly, classical MLE tend to be more prevalent. However it may not always be prudent to assume that prior is uniform, especially in the cases where prior knowledge of the estimate is available even though the exact PDF is unknown. In these cases a MAP estimate may perform better even if an “artificial” prior PDF is assumed (e.g., a Gaussian prior which has the added benefit of yielding a Gaussian posterior).